The Uzbek alphabet is approaching the Turkic world and artificial intelligence
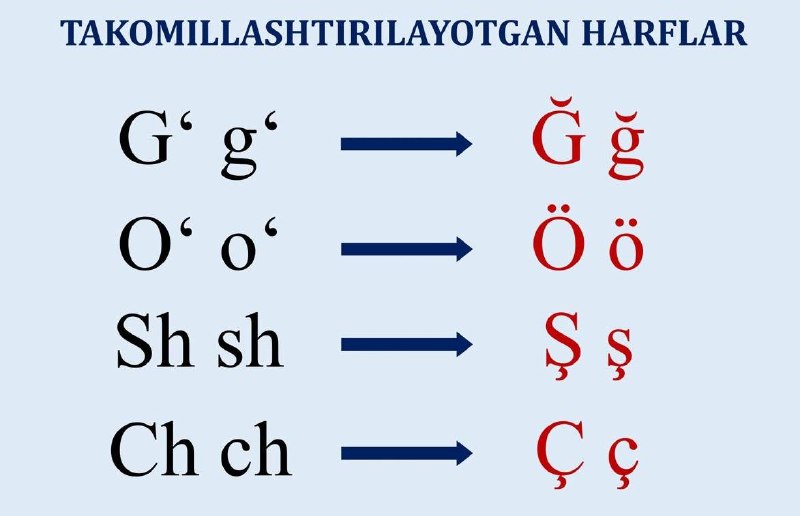
Most people associate the changes in the alphabet only with the letters Ş, Ç, Ğ and Ö. In fact, it is about another matter.
In today's world, artificial intelligence, search engines, e-government services, automatic translation, voice assistants and digital archives rely primarily on how computers, not humans, perceive language. In the current alphabet, letters consisting of two characters, such as O, G, Sh and Ch, are considered by computer systems not as one letter, but as two separate characters.
And this:
teaching artificial intelligence in Uzbek;
electronic government services;
search engines;
automatic translations;
causes technical difficulties in working with digital archives.
Therefore, the proposed changes are not aimed at improving the language, but its digital capabilities.
Most importantly, this approach is also compatible with the All-Turkish alphabet project developed by the scientists of the Organization of Turkic States in Baku in 2024.
The proposed changes serve to make the Uzbek language more suitable for 21st century technologies, digital environment and artificial intelligence.
https://t.me/Rasmiy_akhborot_official